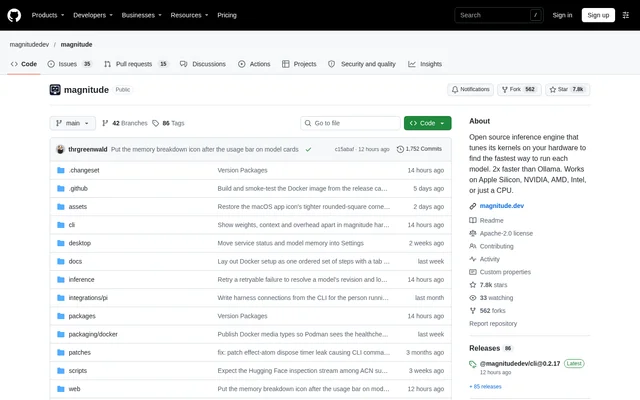
What is Magnitude?
Magnitude is an open-source inference engine that runs open models and optimizes their kernels for the hardware available. Magnitude is designed for developers and people using AI agents who want models to run on their own machines. The project provides a desktop app and CLI, supports macOS, Linux, and Windows, and connects local models to existing agents rather than requiring users to replace their agent workflow.
Magnitude supports Apple Silicon, NVIDIA, AMD, and Intel GPUs, along with CPU-only operation. The source specifies no fixed hardware minimum: smaller machines run smaller models, while additional memory allows larger models. Magnitude keeps prompts, files, and models on the user's machine and does not require internet access after a model has been downloaded.
What Magnitude can do
Magnitude combines hardware-specific inference optimization with features for running agent workloads locally. Magnitude tunes each downloaded model, includes speculative decoding drafters, and manages memory across agent sessions. The project also provides direct connections to named agents and an API path for other clients, allowing local inference to fit into existing development workflows.
- Magnitude automatically tunes kernels for each model on the user's hardware.
- Magnitude includes a speculative decoding drafter with each model.
- Magnitude uses quantized KV memory that is freed when agents stop.
- Magnitude shares prefix caches across concurrent sessions.
- Magnitude connects to Pi, OpenCode, Hermes, Codex, Claude Code, and Cline.
- Magnitude supports other clients through an OpenAI-compatible API.
How Magnitude works
Magnitude can be installed through terminal commands or downloaded installers, with both desktop and CLI interfaces available. When a user downloads a model, Magnitude tests different ways to divide computation on the actual chip and retains the fastest combination that does not change the model's output. The source says this tuning can take up to a minute.
Magnitude offers agent connections through a single-click workflow and supports additional clients through an OpenAI-compatible API. Magnitude also provides documentation for running as a remote service accessible to other computers and for running in Docker. The supported model list is published at magnitude.dev/models, with optimized kernels focused on popular open-weight families.
Who Magnitude is for
Magnitude serves developers and AI agent users who want to run open models on their own hardware. Magnitude supports workflows involving existing coding agents, offline model use, and concurrent sessions. Users can choose local desktop or CLI operation, or consult the remote-server documentation when other computers need access to the inference service.
- Magnitude can supply local models to existing coding agents.
- Magnitude can run downloaded models without an internet connection.
- Magnitude can support concurrent agent sessions with shared prefix caches.
- Magnitude can run as a service that other computers use.
Magnitude pricing and access
Magnitude is free and open source under the Apache 2.0 license, and the project states that there are no token costs. Magnitude is available through the public repository, terminal installation commands, and downloadable installers. Installer options cover macOS on Apple silicon and Intel, Windows x64, and Linux packages for x64 and ARM64.
Magnitude strengths and limitations
Magnitude combines local data handling, hardware-specific tuning, and connections to existing agents. Magnitude also supports multiple operating systems and both GPU and CPU execution. These capabilities make the project relevant to local inference workflows, but model choice and model size still depend on the supported model families and the memory available on the user's machine.
- Magnitude requires a model download before offline use.
- Magnitude adds hardware-tuning time when a model is downloaded.
- Magnitude runs larger models only when sufficient memory is available.
- Magnitude focuses optimized kernels on popular open-weight model families.
Magnitude FAQ
What is Magnitude?
Magnitude is an open-source inference engine that runs open models and automatically tunes their kernels for local hardware. Magnitude includes a desktop app and CLI and connects local models to existing AI agents through direct connections or an OpenAI-compatible API.
Is Magnitude free?
Magnitude is free and open source under the Apache 2.0 license, with no token costs. Magnitude is available through terminal installation commands and downloadable installers, with desktop and CLI interfaces for supported operating systems.
What hardware and operating systems does Magnitude support?
Magnitude supports macOS, Linux, and Windows on Apple Silicon, NVIDIA, AMD, or Intel GPUs, as well as CPU-only machines. Magnitude has no fixed hardware minimum, but smaller machines run smaller models and more memory enables larger models.
Which agents work with Magnitude?
Magnitude offers single-click connections to Pi, OpenCode, Hermes, OpenClaw, Codex, Claude Code, Oh My Pi, and Cline. Magnitude also provides an OpenAI-compatible API so other clients can connect to models running through the inference engine.
Can Magnitude run offline?
Magnitude can run without internet access once a model has been downloaded. Magnitude keeps prompts, files, and models on the user's machine, making local model execution available without sending those materials to an external inference service.
How does Magnitude optimize model inference?
Magnitude automatically tunes model kernels on the user's actual hardware during model download. Magnitude tests different ways to split computation and keeps the fastest combination that does not change the model's output, with tuning taking up to a minute.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.