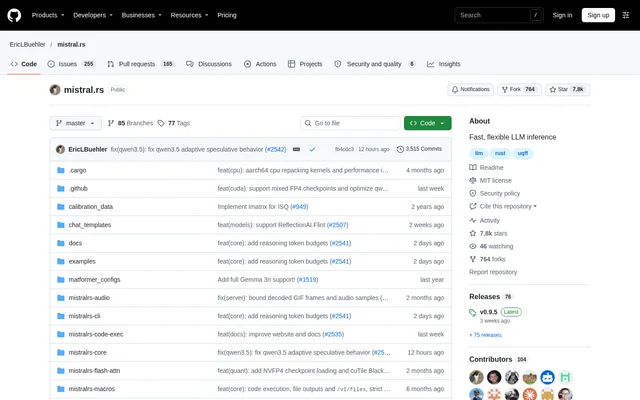
What is mistral.rs?
mistral.rs is an open-source inference engine for running language and multimodal models. mistral.rs supports developers who need a local model server, embedded inference, or an agent runtime. The repository provides a command-line application, browser interface, HTTP APIs, and SDKs rather than a single-purpose chat application.
mistral.rs supports text, vision, video, audio, speech generation, image generation, and embeddings. The repository identifies supported model architectures through documentation generated from the engine's loader registry. The project is distributed under the MIT license, and the README explicitly states that mistral.rs is not affiliated with Mistral AI.
What mistral.rs can do
mistral.rs combines model inference, quantization, and agent execution in one engine. Supported Hugging Face models and GGUF files can use automatic architecture, weight-format, and chat-template detection. Serving capabilities include continuous batching, prefix caching, and multi-GPU or distributed inference, with acceleration options including CUDA and Metal.
- mistral.rs runs supported text, image, video, audio, and embedding models.
- mistral.rs exposes OpenAI-compatible and Anthropic-compatible API endpoints.
- mistral.rs provides browser chat with inline reasoning, code execution, plots, and files.
- mistral.rs executes tools through web search, persistent Python sessions, and shell sessions.
- mistral.rs connects external tools through an MCP client using Process, HTTP, or WebSocket.
- mistral.rs supports LoRA selection per request and X-LoRA adapter mixing.
How mistral.rs works
mistral.rs can be installed from a terminal using the documented macOS, Linux, or Windows installer. After installation, users open a new terminal and start a model with the serve command. The server exposes a browser interface at /ui by default, alongside compatible HTTP endpoints for application and agent requests.
mistral.rs also supports in-process inference through the Python package and embedding through the Rust crate. Python applications load a model with Runner and send OpenAI-shaped requests without a separate server. Prebuilt CPU and CUDA Docker images are published to GHCR, while the documentation covers accelerator-specific wheels, container deployment, and Kubernetes notes.
Who mistral.rs is for
mistral.rs is suited to developers integrating model inference into applications or connecting coding agents to local models. Python and Rust SDKs address embedded application workflows, while compatible HTTP endpoints support server-based integrations. Built-in tool execution and session management also support agent workflows that combine model responses with scripts, files, and external tools.
- Developers can point Claude Code or Codex at a locally served coding model.
- Application builders can embed inference through Python or Rust.
- Agent developers can combine tool calling with code execution and uploaded Skills.
- Model-serving teams can collect request counts and latency through Prometheus metrics.
mistral.rs pricing and access
mistral.rs is available as an open-source project under the MIT license. Access options include the public repository, terminal installers, a Python package, a Rust crate, and prebuilt Docker images. The supplied project text describes software installation and deployment rather than a hosted subscription service or paid plan structure.
mistral.rs strengths and limitations
mistral.rs offers several integration paths without requiring every application to use a separate inference server. Automatic model detection and hardware-aware tuning can assist configuration, while compatible APIs connect local models to existing coding-agent workflows. Model and hardware support still require checking the documentation, particularly when selecting architectures, accelerator packages, quantization formats, or device mappings.
- Model loading depends on supported architectures and identifiable model metadata.
- Accelerator-specific packages and configuration differ across hardware backends.
- The browser chat quickstart requires the serving terminal to remain open.
mistral.rs FAQ
What is mistral.rs?
mistral.rs is an open-source LLM inference engine for text and multimodal models. mistral.rs provides a command-line server, browser interface, compatible HTTP APIs, and Python and Rust SDKs for developers building local applications and agent workflows.
Is mistral.rs free?
mistral.rs is available as an open-source project under the MIT license. The repository provides installation instructions, Python and Rust packages, and Docker deployment options rather than describing a paid subscription plan.
Does mistral.rs work with Claude Code and Codex?
mistral.rs supports Claude Code and Codex through a locally served model. The same serving process exposes OpenAI-compatible endpoints and Anthropic-compatible Messages endpoints, and the documentation includes setup instructions for connecting these coding agents.
Can mistral.rs run models directly from Python?
mistral.rs supports in-process Python inference without a separate server. Developers install the Python package, load a model with Runner, and send OpenAI-shaped requests. The getting-started guide lists accelerator-specific wheels for CUDA, Metal, MKL, and Accelerate.
What agent tools does mistral.rs support?
mistral.rs includes web search, persistent Python code execution, shell execution, uploaded Skills, session management, and custom tool hooks. An MCP client connects external tools through Process, HTTP, or WebSocket, while Python and Rust callbacks support custom execution.
Which models can mistral.rs run?
mistral.rs supports text, multimodal, speech, image-generation, and embedding models. The supported-models reference lists architectures and run commands and explains how to check a model's config.json. Automatic loading detects supported Hugging Face architectures and GGUF files.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.